Introduction
One of the most powerful things a web developer can do is fetching data from a server and displaying it creatively on their site. In many cases, the server solely exists for that specific site. The server could contain blog posts, user data, high scores for a game or anything else. In other cases, the server is an open service that serves data to anyone that wants to use it (i.e. weather data or stock prices). In either case, the methods of accessing and then using that data are essentially the same.
Lesson overview
This section contains a general overview of topics that you will learn in this lesson.
- What APIs are.
- How access to an API works.
- How to fetch and extract data from an API.
APIs
Servers created to provide functionality and serve data for external use (in websites or apps) often do so using Application Programming Interfaces (APIs).
There are multiple ways of requesting data from an API, but all of them basically do the same thing. For the most part, APIs are accessed through URLs, and the specifics of how to query these URLs change based on the specific service you are using. For example, GIPHY has an API for GIFs. You can check out the GIPHY API documentation for more specific usage information. To get a random cat GIF from GIPHY’s API, you can pass search queries into a URL like so:
https://api.giphy.com/v1/gifs/random?rating=g&tag=cats
Go ahead and paste the URL above into your browser (we’ll wait).
You’ll probably get an HTTP error response like this:
{
  "data": [],
  "meta": {
    "status": 401,
    "msg": "Unauthorized",
    "response_id": ""
  }
}
This brings us to another point about many APIs: keys.
API keys
In many cases, you will have to create an account and request an “API key” from the API service before attempting to fetch data from their endpoints (specific URLs that you use to access a particular function or data within the API). Once obtained, an API key will usually have to be included with every data request in some way. With GIPHY, that’s as a query string parameter:
https://api.giphy.com/v1/gifs/random?rating=g&tag=cats&api_key=8472697968737880827974696784
As you can imagine, an API key is random and unique to you. As such, services like GIPHY can correlate your API key to your requests of their data, including what you’re requesting and how often you are requesting it.
Issuing API keys allows an API service to better track abuse of their systems and data. Additionally, it can also be a way for those services to mitigate and recuperate operating costs. After all, running servers costs money and APIs are no exception! While a single request to an API might cost a fraction of a penny, imagine using that API to create an amazing images app that gets used all over the world… you could easily have thousands of people accessing that data every minute! The cost to handle that traffic could quickly balloon up to significant sums for the API service.
As such, you’ll find that many API services provide paid tiers that come with the ability to make more frequent requests, or provide access to more information unavailable in lower tiers. For example, the GIPHY API has a free version that allows 100 calls (a.k.a. requests) per hour. On the other hand, the production version provides unlimited API calls for a custom pricing agreement. So if your app becomes successful and needs additional features, you’ll probably need to pay for a better account.
API attribution
In many cases, APIs will require some form of attribution for use in apps, especially ones allowing free use. Attribution instructions would usually be detailed in their documentation in some way if required. For example, GIPHY API attribution involves displaying “Powered By GIPHY” wherever the API is being used.
Because your API key is your key to these services and data, securing them is an important habit, especially if you are using a paid tier. There are plenty of bots that crawl GitHub repositories solely for hardcoded/unsecured API keys, allowing bad agents to then access and utilize the services and data you’ve paid for. In fact, the more eagle-eyed readers may have noticed a problem with the demonstration above: The API key is right there in the URL request. Since the URL would be sent from the client (a browser), it would not take much for an internet traffic sniffer to pick up on the API key, least of all someone looking over your shoulder!
At this point in the curriculum, though, this point is largely moot. After all, we’re leveraging free access to APIs, and the majority of our apps are only going to be used by us and the people that view our portfolios. Just make a note of the severe limitations of using API keys as demonstrated above for now. Securing API keys requires handling things server-side, and we are only focusing on the frontend concepts here. If you are in the Full Stack JavaScript pathway, the back end will be covered later in the curriculum.
Back to GIPHY. Go ahead and create a free GIPHY account then head over to the GIPHY developer dashboard to obtain an API key. Once you have your key, try the previous request again but with your key passed in as the api_key query string parameter. You’ll hopefully see a proper response, something like this (which we’ve truncated):
{
  "data": {
    "type": "gif",
    "id": "LgKYWVyOtjtHgJlXhE",
    "url": "https://giphy.com/gifs/night-led3an-led3-LgKYWVyOtjtHgJlXhE",
    "slug": "night-led3an-led3-LgKYWVyOtjtHgJlXhE",
    "bitly_gif_url": "https://gph.is/g/aKPMvql",
    "bitly_url": "https://gph.is/g/aKPMvql",
    "embed_url": "https://giphy.com/embed/LgKYWVyOtjtHgJlXhE",
    "username": "led3an",
    "source": "",
    "title": "You And Me Love GIF",
    "rating": "g",
    "content_url": "",
    "source_tld": "",
    "source_post_url": "",
    "is_sticker": 0,
    "import_datetime": "2026-09-18 05:04:13",
    "trending_datetime": "0000-00-00 00:00:00",
    "images": {
      "original": {
        "height": "450",
        "width": "450",
        "size": "6631786",
        "url": "https://media0.giphy.com/media/v1.Y2lkPTRhYzNiM2FhZGEycnB5d2lxM2pmZW83eHZhMzNxejE4a3FobHd3bG13bHF2eXhoNCZlcD12MV9naWZzX3JhbmRvbSZjdD1n/LgKYWVyOtjtHgJlXhE/giphy.gif",
        "mp4_size": "405600",
        "mp4": "https://media0.giphy.com/media/v1.Y2lkPTRhYzNiM2FhZGEycnB5d2lxM2pmZW83eHZhMzNxejE4a3FobHd3bG13bHF2eXhoNCZlcD12MV9naWZzX3JhbmRvbSZjdD1n/LgKYWVyOtjtHgJlXhE/giphy.mp4",
        "webp_size": "1329736",
        "webp": "https://media0.giphy.com/media/v1.Y2lkPTRhYzNiM2FhZGEycnB5d2lxM2pmZW83eHZhMzNxejE4a3FobHd3bG13bHF2eXhoNCZlcD12MV9naWZzX3JhbmRvbSZjdD1n/LgKYWVyOtjtHgJlXhE/giphy.webp",
        "frames": "65",
        "hash": "6ebcf82d860832b690c6bb00e946c23e"
      },
// and more ...
Congratulations on making your first API request!
Fetching data
So how do we actually get the data from an API into our code?
A couple of years ago the main way to access API data in your code was using an XMLHttpRequest. This function still works in all browsers, but unfortunately, it is not particularly nice to use. The syntax looks something like this:
// Just getting XHR is a mess!
if (window.XMLHttpRequest) { // Mozilla, Safari, ...
  request = new XMLHttpRequest();
} else if (window.ActiveXObject) { // IE
  try {
    request = new ActiveXObject('Msxml2.XMLHTTP');
  } catch (Msxml2Error) {
    try {
      request = new ActiveXObject('Microsoft.XMLHTTP');
    } catch (MicrosoftError) {

    }
  }
}

// Open, send.
request.open('GET', 'https://url.com/some/url', true);
request.send(null);
Ouch. That was painful.
Developers, feeling the pain of having to write that stuff out, began writing 3rd party libraries to take care of this and make it much easier to use. Some of the more popular libraries are axios and superagent, both of which have their strengths and weaknesses.
Nowadays, however, web browsers have a simpler native function for making HTTP requests, and that’s the one we’re going to use and stick with for now. Meet fetch:
// URL (required), options (optional)
fetch('https://url.com/some/url')
  .then(function(response) {
    // Successful response :)
  })
  .catch(function(err) {
    // Error :(
  });
In case you’ve forgotten, scroll back up and look at how you would use XHR to do the same thing. While you’re admiring how nice and clean that code is, notice the .then() and .catch() functions there. Do you remember what those are? (PROMISES!)
Let’s walk through an example using fetch with the GIPHY API to display a random GIF on a webpage.
Giphy has several methods for searching and finding GIFs which you can read about in their documentation. We’ll stick with the random endpoint because it’s the simplest one for our purposes. You can find the appropriate URL in the Giphy random endpoint documentation. What it tells us is that the correct URL is api.giphy.com/v1/gifs/random and that it requires an api_key parameter. There are other optional parameters that you could include in your query, such as the tag parameter to narrow down what GIF could be returned, as well as the rating parameter which allows you to look for content at different levels of sensitivity. That’s how we got the full API URL earlier.
Let’s do this
For now, we’re going to keep all of this in a single HTML file. So go ahead and create one with a single blank image tag and an empty script tag in the body.
<!DOCTYPE html>
<html lang="en">
<head>
  <meta charset="UTF-8">
  <title>Document</title>
</head>
<body>
  <img src="#">
  <script>
  </script>
</body>
</html>
In the script tag, let’s start by selecting the image element and assigning it to a variable so that we can change the URL once we’ve received it from the GIPHY API.
<script>
  const img = document.querySelector('img');
</script>
Adding fetch with our URL from above is also relatively easy:
<script>
  const img = document.querySelector('img');
  fetch('https://api.giphy.com/v1/gifs/random?api_key=YOUR_KEY_HERE&tag=cats&rating=g')
    .then(function(response) {
      console.log(response.json());
    });
</script>
You should now be able to open the HTML file in your browser, and while you won’t see anything on the page, you should have something logged in the console. The trickiest part of this whole process is deciphering how to get to the data you desire from the server’s response. In this case, inspecting the browser’s console will reveal that what’s being returned is another Promise… to get the data we need another .then() function.
<script>
  const img = document.querySelector('img');
  fetch('https://api.giphy.com/v1/gifs/random?api_key=YOUR_KEY_HERE&tag=cats&rating=g')
    .then(function(response) {
      return response.json();
    })
    .then(function(response) {
      console.log(response);
    });
</script>
Now we have a JavaScript object and if you inspect it closely enough you’ll find that the data we need (an image URL) is nested rather deeply inside the object:
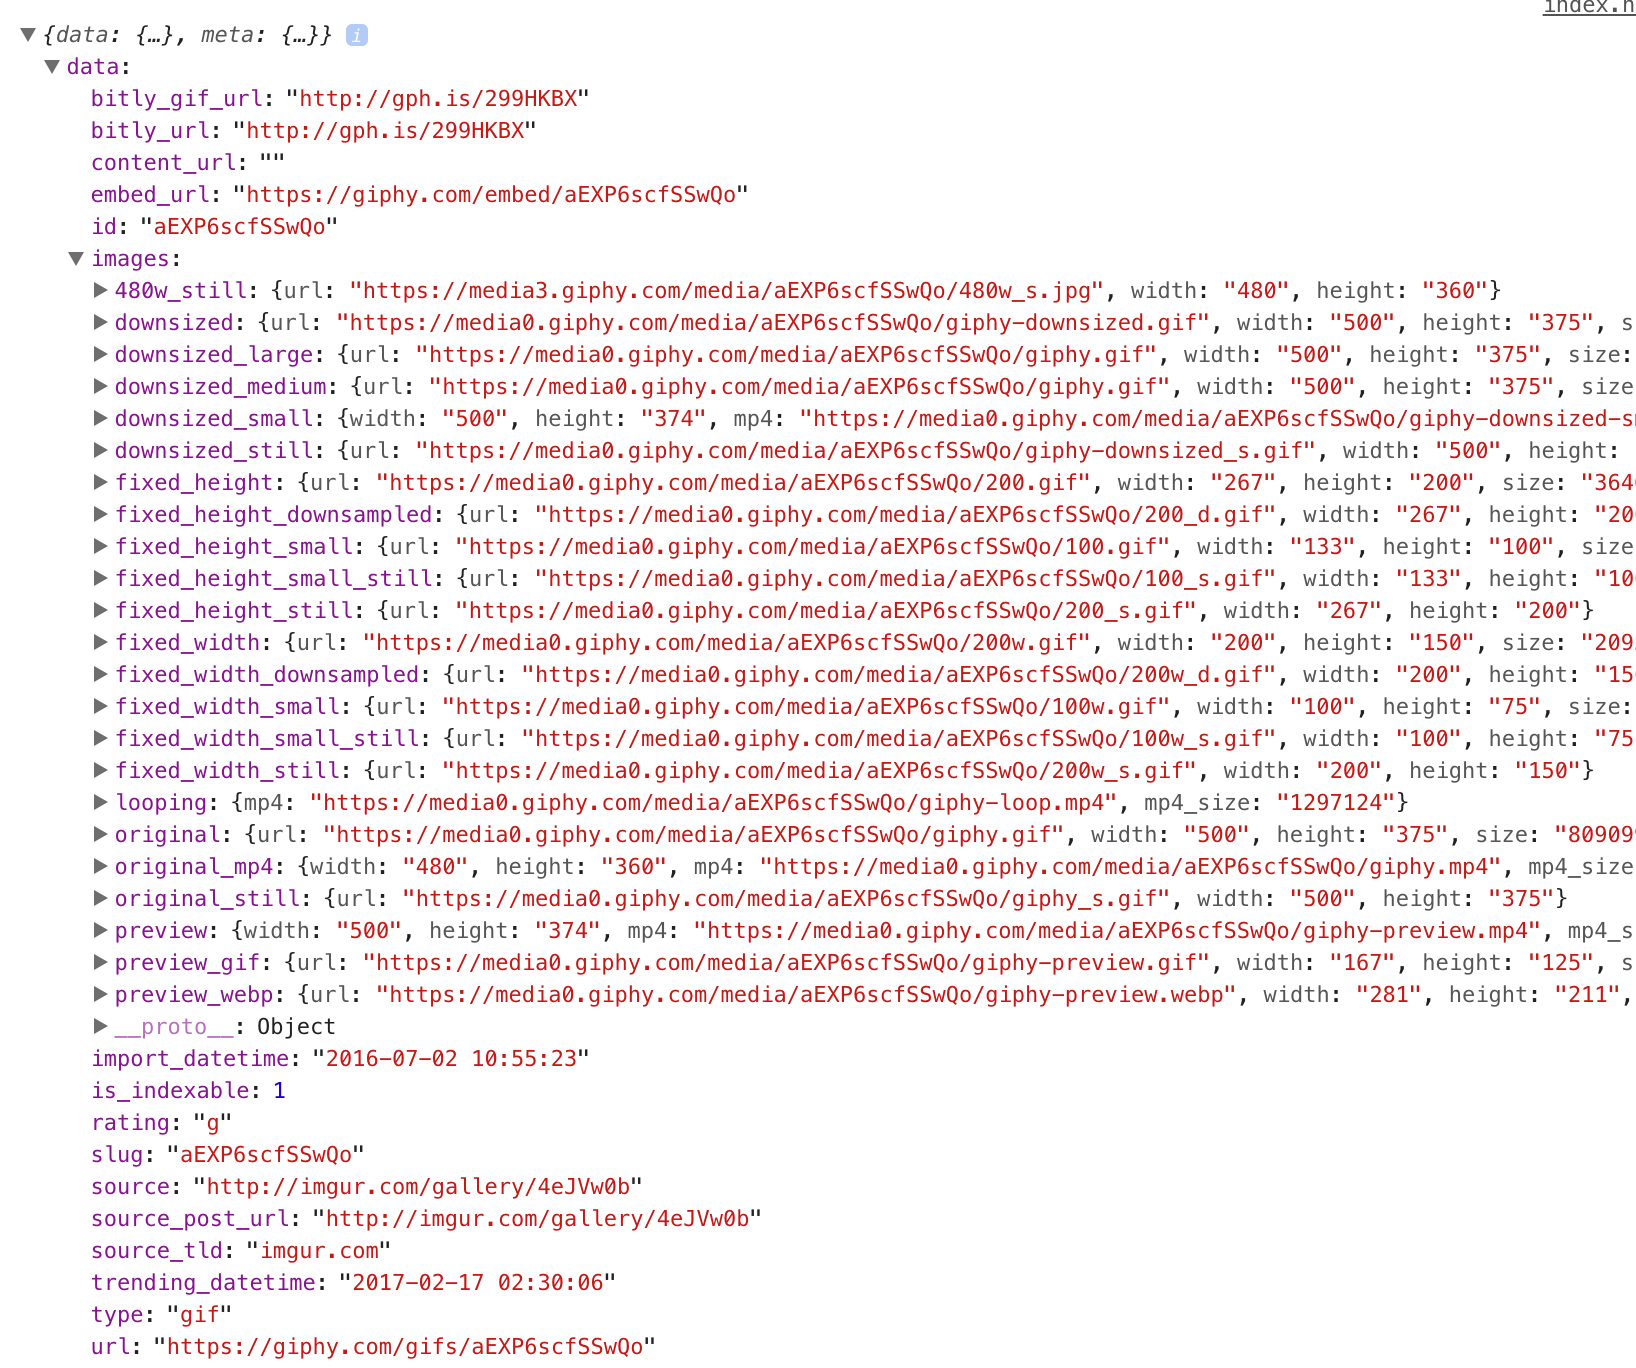
To get to the data we need to drill down through the layers of the object until we find what we want!
<script>
  const img = document.querySelector('img');
  fetch('https://api.giphy.com/v1/gifs/random?api_key=YOUR_KEY_HERE&tag=cats&rating=g')
    .then(function(response) {
      return response.json();
    })
    .then(function(response) {
      console.log(response.data.images.original.url);
    });
</script>
Running the file should now log the URL of the image. All that’s left to do is set the source of the image that’s on the page to the URL we’ve just accessed:
<script>
  const img = document.querySelector('img');
  fetch('https://api.giphy.com/v1/gifs/random?api_key=YOUR_KEY_HERE&tag=cats&rating=g')
    .then(function(response) {
      return response.json();
    })
    .then(function(response) {
      img.src = response.data.images.original.url;
    });
</script>
If all goes well, you should see a randomly selected image on the page every time you refresh!
Assignment
- Check out this list of Public APIs and let your imagination go wild.
- Expand on our little project here by adding a button that fetches a new image without refreshing the page.
-
Add a search box so users can search for specific GIFs. You should also investigate adding a
.catch()to manage some errors (e.g. invalid URL). Keep in mind that if the API responds, even with something like a404 Not Foundor some other non-2XX status response, that is still a valid response andfetchwill therefore not throw an error, meaning the.catch()will not run. It may still end up running if your following JavaScript code throws an error, such as trying to access a property ofundefined, or even if you manually throw an error yourself.If you want to conditionally handle any situations where the API does not give you the desired response (e.g. a
404 Not Foundor similar), you will need to do this manually in your.then(). Check out MDN’s docs for the Response object for some useful properties.